NVIDIA used its IFA 2026 stage to launch PAIR (Personal AI Router), a free, open-source application that distributes AI agent workloads across multiple home PCs, and confirmed that RTX Spark Windows systems will ship in October 2026 from over half a dozen OEM partners.
PAIR: Distributed Inference For Home Networks
PAIR addresses a specific bottleneck in local AI: agent workflows that split complex tasks into parallel subtasks often bottleneck when every request competes for a single GPUGPU. Graphics Processing Unit — the chip that renders the game's visuals; the main driver of framerate and image quality.. The app automatically detects compatible PCs on a local network and routes independent inference requests to whichever system has available capacity. It integrates with Ollama and LM Studio, and adapts dynamically as devices join or leave the network.
In NVIDIA’s benchmark, a single RTX Spark laptop running Qwen3.6-35B through Ollama completed a simulated five-subagent inbox-sorting task in roughly 18 minutes. The same task distributed across three devices—an RTX Spark laptop, a DGX Spark, and an RTX 5090 desktop—finished in 8 minutes and 48 seconds.
The PAIR beta is available immediately for download from NVIDIA’s AI-on-RTX page and supports Windows, macOS, and Linux. Hardware compatibility covers GeForce RTX 20 Series and newer, NVIDIA RTX PRO workstation GPUs, NVIDIA DGX Spark, and Apple M4 silicon.
RTX Spark Hardware Arriving October
RTX Spark Windows PCs will arrive in compact desktop and thin-and-light laptop form factors from OEM partners including ASUS, Dell, HP, Lenovo, Microsoft Surface, and MSI. Lenovo has already announced the Yoga Pro 9n and Yoga 9n 2-in-1 as part of the initial lineup.
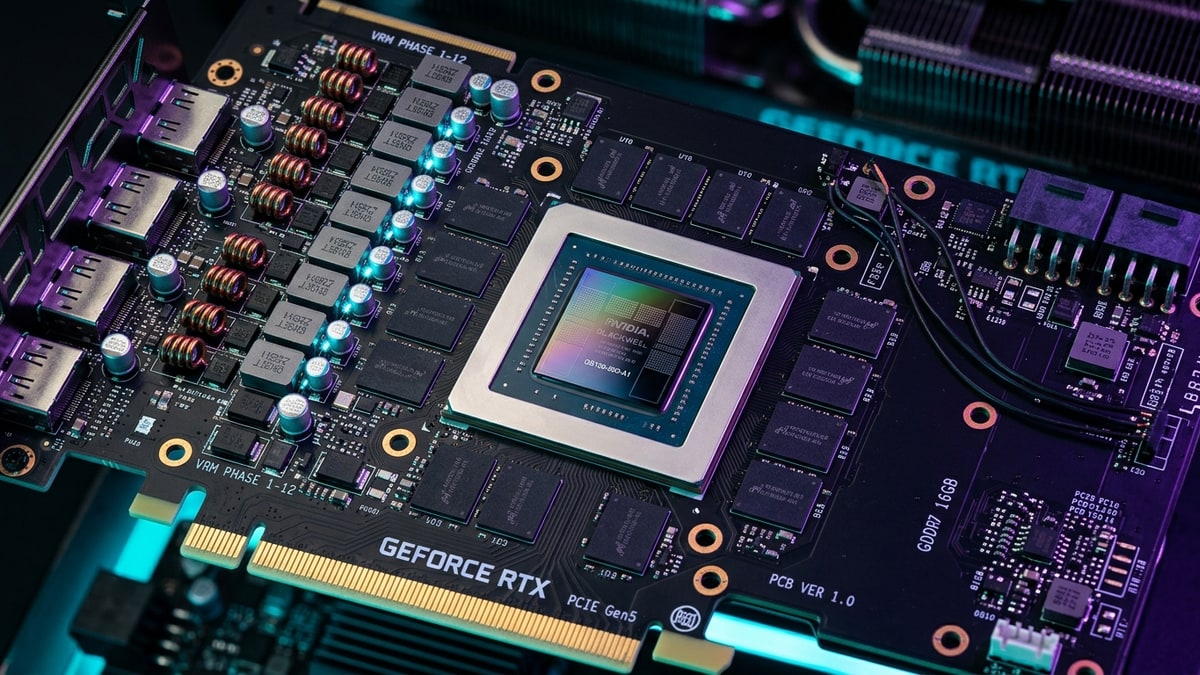
Two configurations of the RTX Spark N1X chip are confirmed. The high-end variant pairs a 20-core NVIDIA Grace CPU with a 6,144-core RTX Blackwell GPU and up to 128GB of unified memory, delivering up to 1 petaflop of local AI compute. The lower-tier configuration scales down to an 18-core CPU, a 5,120-core Blackwell GPU, and 32GB of unified memory. NVIDIA has not announced official pricing.
Software Ecosystem And Adoption
On the inference side, the llama.cpp backend now delivers up to 1.9x higher throughput on the GeForce RTX 5090 through kernel optimizations, enhanced speculative decoding, and faster prefill. vLLM gains range from 1.2x on the RTX PRO 6000 Blackwell Workstation Edition to 1.4x4X. eXplore, eXpand, eXploit, eXterminate — a grand-strategy subgenre about building a civilization over a long arc. on two-DGX Spark clusters.
Major game publishers supporting the RTX Spark platform include EA, Ubisoft, Capcom, and CD Projekt Red. Simplified local AI support is also coming to Hermes Agent, OpenClaw, and Perplexity Portable Computer, each built on llama.cpp with NVIDIA’s inference optimizations applied.